America
Project Panama: Inside Anthropic’s secret race to scan millions of physical books

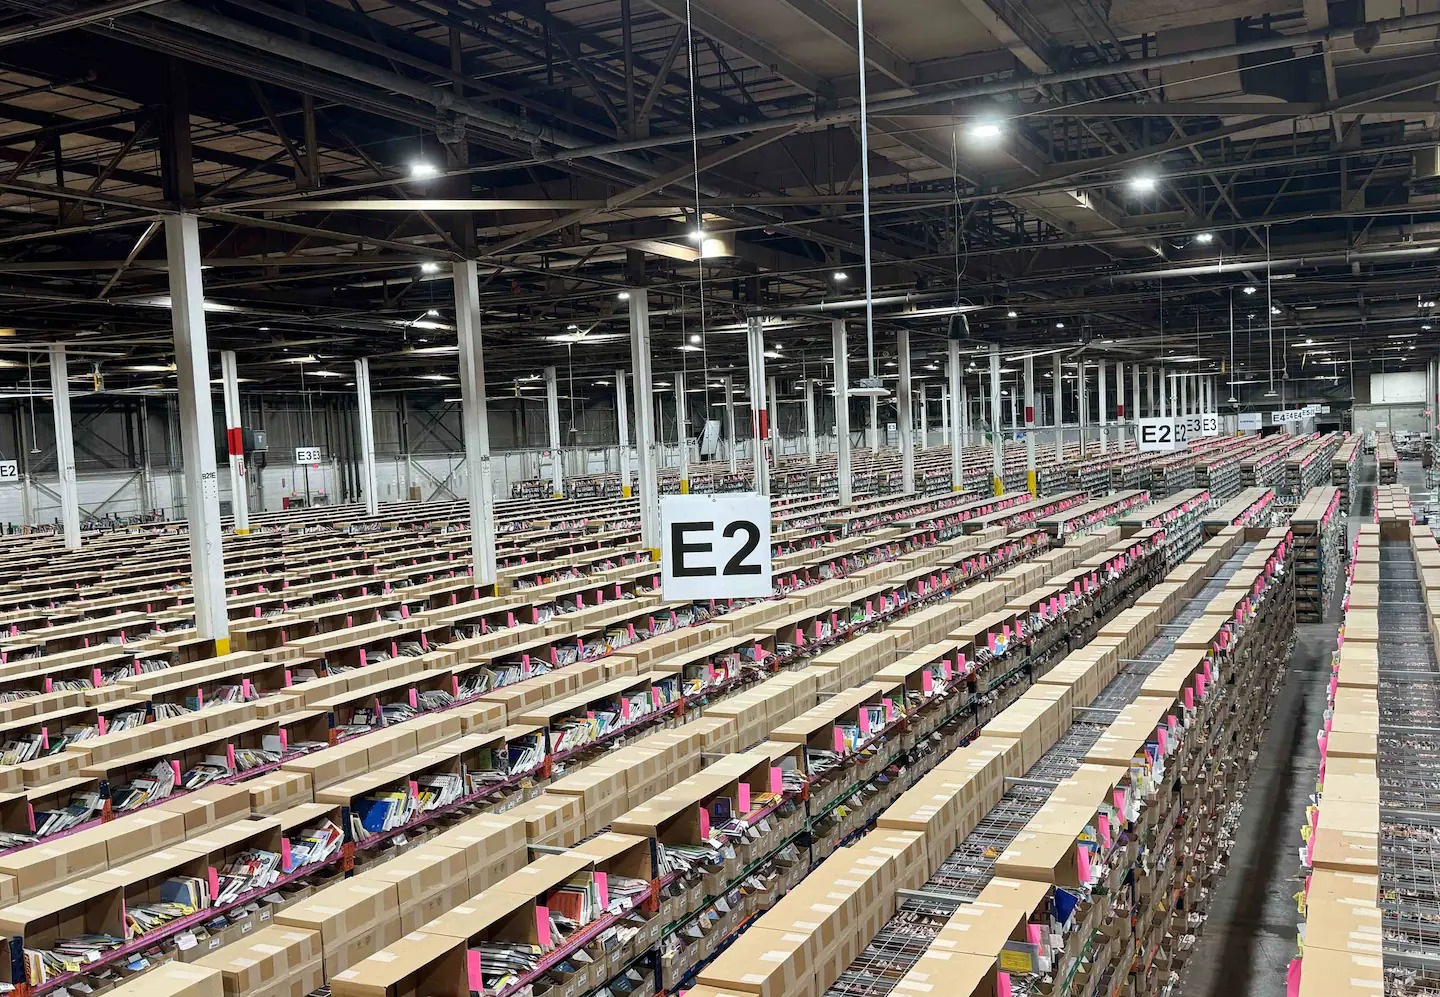
In early 2024, the artificial intelligence startup Anthropic initiated a clandestine operation dubbed “Project Panama,” an effort to “destructively scan” nearly every book in existence.
According to court filings obtained by The Washington Post, the company spent tens of millions of dollars over the course of a year to purchase millions of books and physically dismantle them by cutting off their spines. The pages were then scanned to feed vast quantities of information into the AI models powering products like the popular chatbot Claude.
The previously undisclosed details of Project Panama were revealed in more than 4,000 pages of documents related to a copyright lawsuit brought by authors against Anthropic, which investors recently valued at $183 billion. While the company agreed to a $1.5 billion settlement in August to resolve the case, a district judge’s decision last week to unseal a series of related documents has provided a clearer picture of Anthropic’s aggressive pursuit of literary data.
These new filings, alongside documents submitted in other copyright cases against AI firms, illustrate the extraordinary lengths to which technology giants—including Anthropic, Meta, Google, and OpenAI—have gone to acquire massive troves of data for “training” their software. The Anthropic litigation is part of a broader wave of legal action by authors, artists, photographers, and news organizations who claim their creative works are being exploited.
Court records reveal that these companies view books as a premier prize. In a January 2023 document, one of Anthropic’s co-founders suggested that training AI models on books would teach them “to write well,” rather than merely mimicking “low-quality internet slang.” Similarly, a 2024 internal Meta email described access to digital book archives as “essential” for staying competitive with AI rivals.
However, the records also show that these companies found it “impractical” to obtain direct permission from publishers and authors. Instead, Anthropic, Meta, and others devised ways to acquire books in bulk without the authors’ knowledge. According to court records, these methods included downloading pirated copies.
When Anthropic launched Project Panama to purchase and scan physical books, it turned to a Silicon Valley veteran. The company hired Tom Turvey, a former Google executive who two decades ago helped spearhead the famous but legally controversial Google Books project.
Anthropic initially considered sourcing books from libraries or iconic second-hand bookstores like New York City’s Strand, famous for its “18 miles” of new and used titles. A March 2024 document detailing an Anthropic content acquisition meeting noted that the store “was interested in providing second-hand books.” Documents also show Anthropic employees discussed approaching US libraries, including the New York Public Library or even “a chronically underfunded new library.”
It remains unclear which of these proposals, if any, were executed. A spokesperson for Strand, reached via email, stated that the bookstore did not sell any books to Anthropic.
Ultimately, documents indicate that Anthropic purchased millions of books, often in batches of tens of thousands, relying on used-book retailers such as Better World Books and the UK-based World of Books. While the final number of scanned books and the total cost were redacted in the documents, a project proposal from a vendor working with Anthropic specified that the AI firm was seeking a “document scanning service provider experienced in converting 500,000 to two million books over a six-month period.”
The document explained that the scanning firm’s “hydraulic-driven cutting machine” would “neatly cut” the books, and the pages would then be scanned using “high-speed, high-quality, production-level scanners.” Finally, the vendor would arrange a schedule with a “recycling company to collect the completed books.”
Internal messages show that Meta employees repeatedly expressed concerns that downloading millions of books without permission would violate copyright law. In December 2023, an internal email submitted in the copyright case against Meta noted that the practice was approved after being “communicated to MZ,” an apparent reference to CEO Mark Zuckerberg.
In a recently released legal filing, Anthropic revealed that co-founder Ben Mann personally spent 11 days in June 2021 downloading fiction and non-fiction titles from “LibGen,” a well-known “shadow library” hosting pirated books and other copyrighted content. A screenshot of a web browser included in the files showed Mann using file-sharing software to download the data.
A year later, in July 2022, Mann welcomed the launch of a new website called Pirate Library Mirror, which claimed to host a massive database of books and stated, “we are intentionally violating copyright law in most countries.” Mann sent a link to the site to other Anthropic employees with the message: “just in time!!!”
In legal filings, Anthropic argued that it did not train a commercial AI model for profit using LibGen data and that it never used Pirate Library Mirror to train any completed AI model.
Ed Newton-Rex, a former AI executive and music composer who now leads a non-profit advocating for creators’ rights, said these revelations underscore that AI companies owe creators far more than they have paid to date. “We urgently need a reset in the AI industry so that creators start getting paid fairly for the vital contributions they make,” he said.
Google, Microsoft, and ChatGPT-maker OpenAI face similar copyright lawsuits from authors. While many of these cases remain pending, James Grimmelmann, a professor of digital and information law at Cornell Tech, noted that the legal questions they raise remain unresolved.
However, in two separate rulings, judges determined that tech companies’ use of books to train AI models without author or publisher permission might be legal under the “fair use” doctrine of copyright law. In June, District Judge William Alsup ruled that Anthropic had the right to use books for training because they processed the works in a “transformative” manner. The judge likened the AI training process to teachers “teaching school children how to write well.”
That same month, District Judge Vince Chhabria ruled in the Meta case that authors failed to prove the company’s AI models could harm the sales of their books.
Nevertheless, companies may still face legal jeopardy regarding how they acquired the books. In the Anthropic case, while the scanning project was accepted, the judge ruled that the company may have violated authors’ copyrights by downloading millions of pirated books for free before launching Project Panama. Alsup granted class-action status to authors whose works were included in two shadow libraries that Anthropic downloaded and stored for future use.
Rather than go to trial, Anthropic agreed to pay publishers and authors $1.5 billion without admitting wrongdoing. Authors whose books were downloaded can claim a share of the settlement, estimated at approximately $3,000 per book.
Aparna Sridhar, Anthropic’s deputy general counsel, stated in an email to The Washington Post: “This case has been resolved, but the court’s landmark June 2025 ruling remains valid. Judge Alsup argued that AI training is ‘fundamentally transformative’: Anthropic’s AI models were trained ‘not to copy or replace works, but to get over a difficult hump and create something different.’ What we settled on was how some materials were obtained, not whether we could use them to develop AI models.”
Documents released in the Meta lawsuit suggest that the social media giant’s employees were equally data-hungry and willing to take legal risks to obtain it. While Judge Chhabria sided with Meta on the use of books for training, he allowed authors to proceed with claims that Meta illegally distributed copies of pirated books. The plaintiffs are seeking class-action status for these claims in the Northern District of California.
In that case, authors alleged that Meta’s senior executives considered purchasing books for training but instead opted to download millions of books for free from “torrent” platforms that facilitate online piracy. Internal documents, some previously reported, show Meta employees expressing concerns that their actions were risky or wrong and discussing how to hide their tracks.
One engineer wrote in 2023, “Downloading torrents from a company laptop doesn’t feel right.” The same employee later voiced concern to the legal team that using torrent sites might require sharing pirated works with others, which “might not be legally appropriate.”
A December 2023 email clearly stated that the use of LibGen was approved after Zuckerberg was notified. “After prior notification to MZ, GenAI’s use of LibGen for Llama 3 was approved… with a series of agreed-upon mitigating measures,” the email read, before listing legal and political risks. It noted that media reports suggesting the use of a known pirate dataset like LibGen could “weaken our negotiating position with regulators on these issues.”
By April 2024, internal correspondence showed the company moving to download LibGen and other shadow libraries. Chat logs show one employee asking another why they were using servers rented from Amazon for torrenting instead of Facebook-owned servers. The answer: “to avoid the risk of the activity being traced back to the company.”
In a filing last month, Meta’s lawyers wrote that the company “denies distributing the plaintiffs’ works while downloading training data using torrents.”
In a separate 2023 case, authors accused OpenAI and Microsoft of violating copyright law by using books for AI training. OpenAI, where Mann and Anthropic CEO Dario Amodei worked before founding their own firm, admitted to downloading LibGen but told the court it deleted the files before the launch of ChatGPT.
Justin A. Nelson, an attorney at Susman Godfrey LLP representing authors in both the OpenAI and Anthropic cases, said: “OpenAI fired the opening shot that led to the widespread piracy by AI companies and the exploitation of all human expression.”
Earlier this month, two major publishers applied to join a group of authors and illustrators in a 2023 copyright lawsuit against Google.
Grimmelmann, the Cornell Tech law professor, observed that AI companies “led themselves into a delusion” regarding the use of copyrighted data. The breakthroughs behind tools like ChatGPT began in academic research, where the use of copyrighted material for training is widely accepted, but researchers continued the practice even as AI models became commercialized.
“By the time the tension became apparent, they had invested heavily in incorporating copyrighted data into their workflows and were in a fast-paced, high-stakes competition to launch newer and better models,” Grimmelmann said.







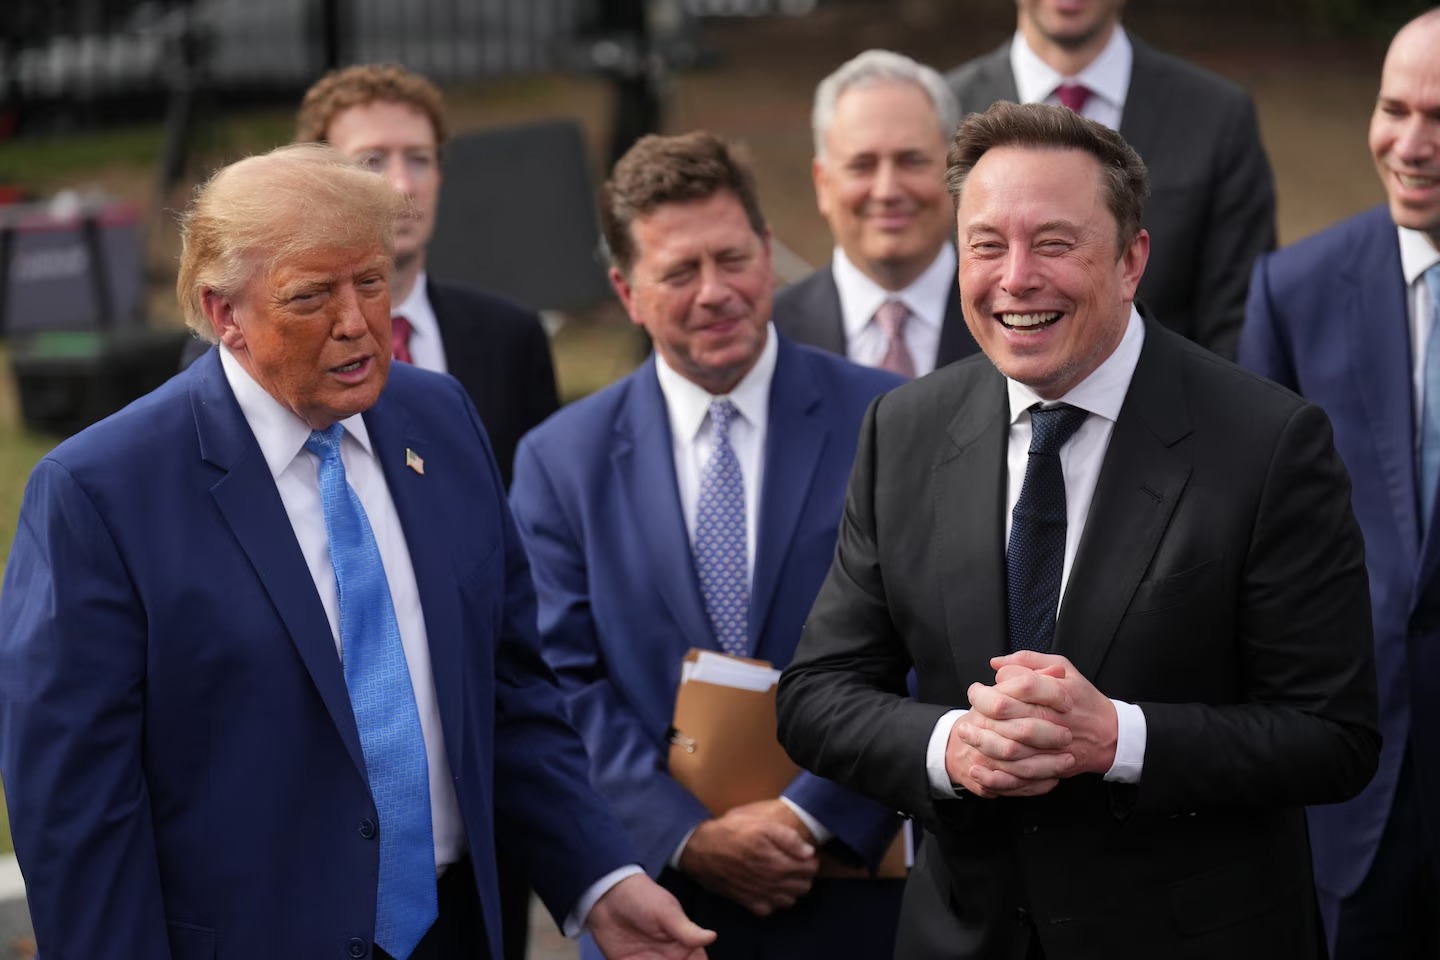
The world’s richest man, Elon Musk, has assumed the co-directorship of a Pentagon initiative focused on the future of warfare, known as “Project Meridian”.
Musk’s new role was announced by US Secretary of Defence Pete Hegseth.
Musk, who has long expressed his conviction that wars will ultimately be fought with autonomous unmanned aerial vehicles, will advise the project as co-director alongside Palmer Luckey, founder of defence start-up Anduril, and former Speaker of the House of Representatives Newt Gingrich.
In a memorandum issued at the Pentagon, Hegseth stated that the group would “examine the battlefields of the future” and “determine which weapons and technologies warfighters must employ to achieve dominance in these environments.”
During his “State of the Force” address at Marine Corps Base Quantico, Hegseth said:
“The best predictors of future conflict do not reside exclusively within the Pentagon. Obvious biases and risks arise when we task ourselves with both framing the questions and answering them.”
Hegseth stated that this initiative would commence immediately and that, following his address, he would convene with Musk, Luckey, and Gingrich at a secure location.
Project Meridian will have 120 days to “ruthlessly map the trajectory of wars, domains, and technologies”, a process that will culminate in the public disclosure of its findings alongside a classified annex.
Hegseth outlined an expansive mandate extending “from beneath the surface of the Earth to beyond the Moon.”
Rather than formulating new military strategies or policies, the panel will seek to identify “the domains we must seize and the capabilities we must master”, focusing on the effort to “discover, develop, and field” the weapons and systems that next-generation American troops may require.
The group is expected to submit a report containing recommendations to him by the end of January.
In 2024, Musk remarked: “Future wars will be entirely about drones and hypersonic missiles.” This was merely one of several similar statements he has made in recent years.
For Musk, whose oversight role at the Department of Government Efficiency (DOGE) ended in turmoil and escalated into a dispute with President Donald Trump over Trump’s spending bill, this appointment marks his formal return to government in an official capacity.
Musk and Trump ultimately reconciled, and Musk attended a meeting on artificial intelligence safety at the White House this week alongside other technology leaders.
Meridian forms part of a broader push announced by Hegseth to restructure the military around autonomous warfare and rapidly advancing technologies.
Hegseth announced the establishment of the Autonomous Warfare Command (AUTOWARCOM), a new four-star combatant command endowed with what he termed “service-like authorities” to scale autonomous and robotic capabilities across the joint force.
The Department of War will also begin phasing in new occupational frameworks across all military branches to establish specialised career tracks for what Hegseth described as “the next generation of autonomous warfighters.”
“We should have conceived an Autonomous Warfare Command a decade ago,” Hegseth said, explaining that Meridian aims to gaze far enough ahead to enable the military to anticipate the next technological shift rather than lag behind.
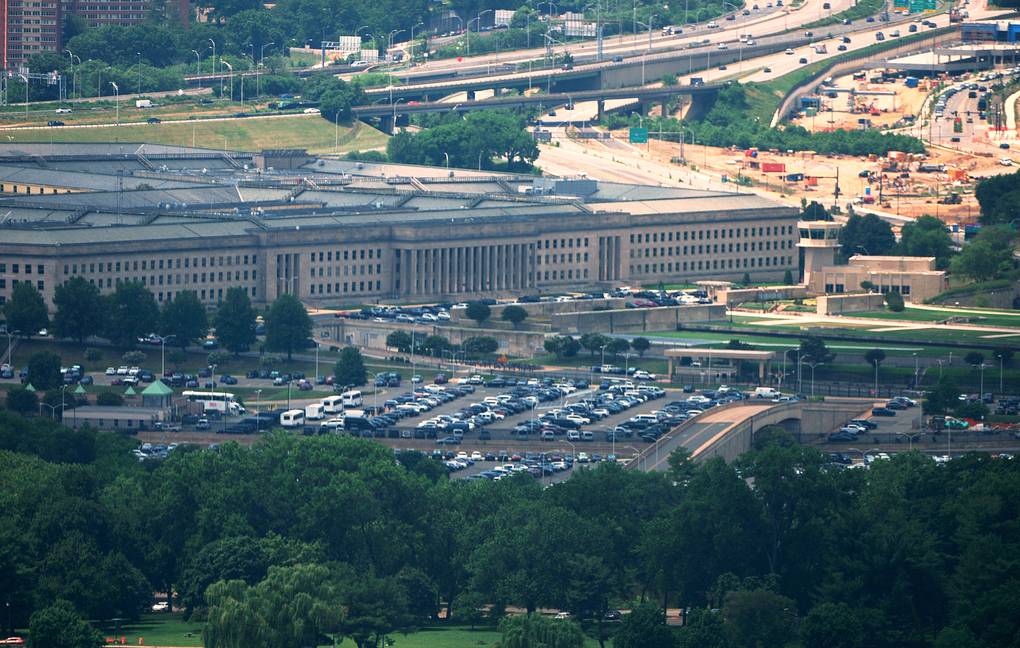
A cyberattack targeting the US Department of War’s personnel database has resulted in the leak of personal information belonging to approximately 3 million people.
Speaking to ABC News, a Pentagon official stated that the system accessed by unauthorised individuals contained the records of 2,760,000 living persons and 294,000 deceased individuals.
The Military Times portal, which first broke the news, had reported the number of affected individuals as approximately 4 million based on two sources. The Pentagon official subsequently conveyed different figures to ABC News.
The leak encompasses Social Security numbers and duty information belonging to military personnel and civilian employees. According to an official notification examined by Military Times, the compromised records may also include names, dates of birth, contact information, sex, race, and military occupational specialties.
The unauthorised access to the information system of the Defense Manpower Data Center (DMDC) lasted for approximately nine months, between October 2025 and 16 July 2026.
ABC News reported that the access in question was obtained by a small number of third-party users. The vulnerability was closed after it was identified.
The DMDC is considered one of the Pentagon’s primary personnel records centres. More than 60 million records belonging to active-duty personnel, reservists, civilian staff, contractors, retirees, veterans, and military family members are stored at the centre.
The Pentagon has not detected any evidence that the leaked data has been misused. Military Times reported that affected individuals were offered identity restoration and credit history monitoring services.
A similar data breach previously occurred on the Federal Bureau of Investigation’s (FBI) recruitment website, FBIJobs.gov. According to information obtained by ABC News from internal communications and sources, the FBI is considering the possibility that data belonging to its entire staff may have been stolen.
The New York Times (NYT) examined a portion of the stolen FBI records. Home addresses, telephone numbers, official email addresses, Social Security numbers, dates of birth, hiring dates, and emergency contact details for relatives were identified within these documents.
The database also contained unit designations, duty roles, and information regarding the supervisors of personnel. Some records revealed assignments within counterintelligence and counternarcotics units, as well as departments examining threats originating from Russia, China, and Iran.
Ciaran Martin, the former head of the UK National Cyber Security Centre, noted that this type of breach could directly affect the FBI’s operational capabilities.
The hacker group known as ShinyHunters had announced that it had seized medical data and security clearance records alongside files belonging to tens of thousands of active and former FBI employees.
Experts evaluating the matter for the NYT warned that this information could be used to track agents, threaten their families, or compile dossiers by foreign intelligence services.
The ShinyHunters group initially threatened to release the data unless the bureau withdrew an advisory it had published concerning the group’s attack methods.
The group later asserted that it had never intended to leak the information and characterised its action as an advertising campaign.
In a report published in May, Reuters noted that the personal data of US military personnel had been used in surveillance and attack preparations.
According to the agency, Washington’s adversaries gained the ability to pinpoint areas where troops were concentrated by exploiting commercially available location data. US lawmakers at the time criticised the Pentagon for failing to adequately protect the personal data of military personnel.
US President Donald Trump’s trade policy and the Washington administration’s push to increase Venezuelan oil imports are prompting Canada to diversify its energy exports.
According to a report by The Wall Street Journal, recent developments are accelerating Canada’s development of new oil and natural gas projects.
Steps taken by the Ottawa administration, which aspires to become an energy superpower, are seen as potentially strengthening the country’s position in global markets.
In Canada, the world’s fourth-largest oil producer and fifth-largest natural gas producer, the energy sector accounts for approximately one-fifth of total exports.
Almost all of the country’s natural gas exports and approximately 90% of its oil exports go to the US.
The newspaper writes that the trade war with Washington and the atmosphere of confrontation entered into with Iran have heightened Canada’s desire to turn to alternative markets outside the US.
Officials plan to increase shipments of oil and liquefied natural gas (LNG) to European and Asian markets.
Accelerating infrastructure investments in line with this target, Canada is also shortening approval processes. The government is prioritising the construction of an oil pipeline extending specifically to the west coast.
According to the newspaper’s estimate, if major pipeline projects are implemented, Canada’s daily oil transport capacity could rise to 6.8 million barrels by 2034.
Routes heading to the west coast will make up approximately 30% of this capacity.
The Canadian administration is simultaneously advancing LNG export projects. According to the report, these investments could allow approximately 55% of Canadian natural gas exports to be directed to markets outside the US by the early or mid-2030s.
While the government expands tax incentives for the oil and natural gas sector, the province of Alberta also plans to overhaul its royalty system.
However, the newspaper notes that implementing the new projects requires heavy investment, and the process depends on the final decisions taken by producers as well as the completion of regulatory approval processes.
The expansion of pipeline and LNG infrastructure could gradually reduce Canada’s dependence on the US market while raising its share in the global energy market.
The Canadian Prime Minister’s demand to reduce reliance on the US market had also come to the fore in July.
According to Carney’s statement, the province of Alberta submitted a plan for a pipeline spanning more than 1,000 kilometres to the west coast of British Columbia.
Targeted for completion by September 2027, the line will reach the Pacific coast by following an existing corridor through the mountainous terrain.
This shift in energy comes at a time of strained relations with the US. Donald Trump said that if Canada obtains associate member status in the European Union, he could halt trade with Europe in certain sectors and impose high tariffs.
As reported by the Associated Press, Trump characterised such a rapprochement as a “potentially hostile act”.
European Commission President Ursula von der Leyen had proposed opening the path for Canada to become the EU’s first associate member. The terms of this associate membership status, which is not defined in EU treaties, are not yet clear and require the approval of member states to enter into force.
Canada, which does not seek full membership, aims for maximum rapprochement with the EU.
Following Trump’s return to the White House, relations between Washington and Ottawa deteriorated. The Trump administration, which repeatedly called on Canada to become the “51st state” of the US, introduced additional tariffs.
In July, the US began imposing 50% tariffs on certain Canadian-origin goods.

Germany expands North Sea military ports and plans new naval base

Musk appointed co-director of Pentagon future warfare initiative

US waives human rights terms on $320m military aid to Egypt

Putin says Russia did not start war and warns of nuclear risks

European nations unite against US pressure over strategic oil stocks
-
 Europe4 days ago
European unions urge governments to scrap all Palantir deals
-
 Diplomacy4 days ago
East-West Forum in Istanbul highlights irreversible shift to multipolarity
-
 Europe1 week ago
Emmanuel Todd says West faces collapse amid Ukraine and Iran crises
-
 Diplomacy1 week ago
East-West Forum in Istanbul to debate multipolarity and global order
-
 Europe1 week ago
European intelligence chiefs divide over risk of Russian attack
-
 Middle East1 week ago
Sharaa says 7 October must not shape Israel policy on Syria
-
 America1 week ago
Republican support for Trump’s war with Iran drops sharply in polls
-
 Middle East1 week ago
Palestinian factions confront legitimacy crisis at Istanbul talks
